Cloud environments have become an important part of how modern businesses run their applications and services. But as cloud systems grow, managing them manually becomes harder. A small server issue, failed service, memory problem, or unexpected traffic spike can quickly affect an application.
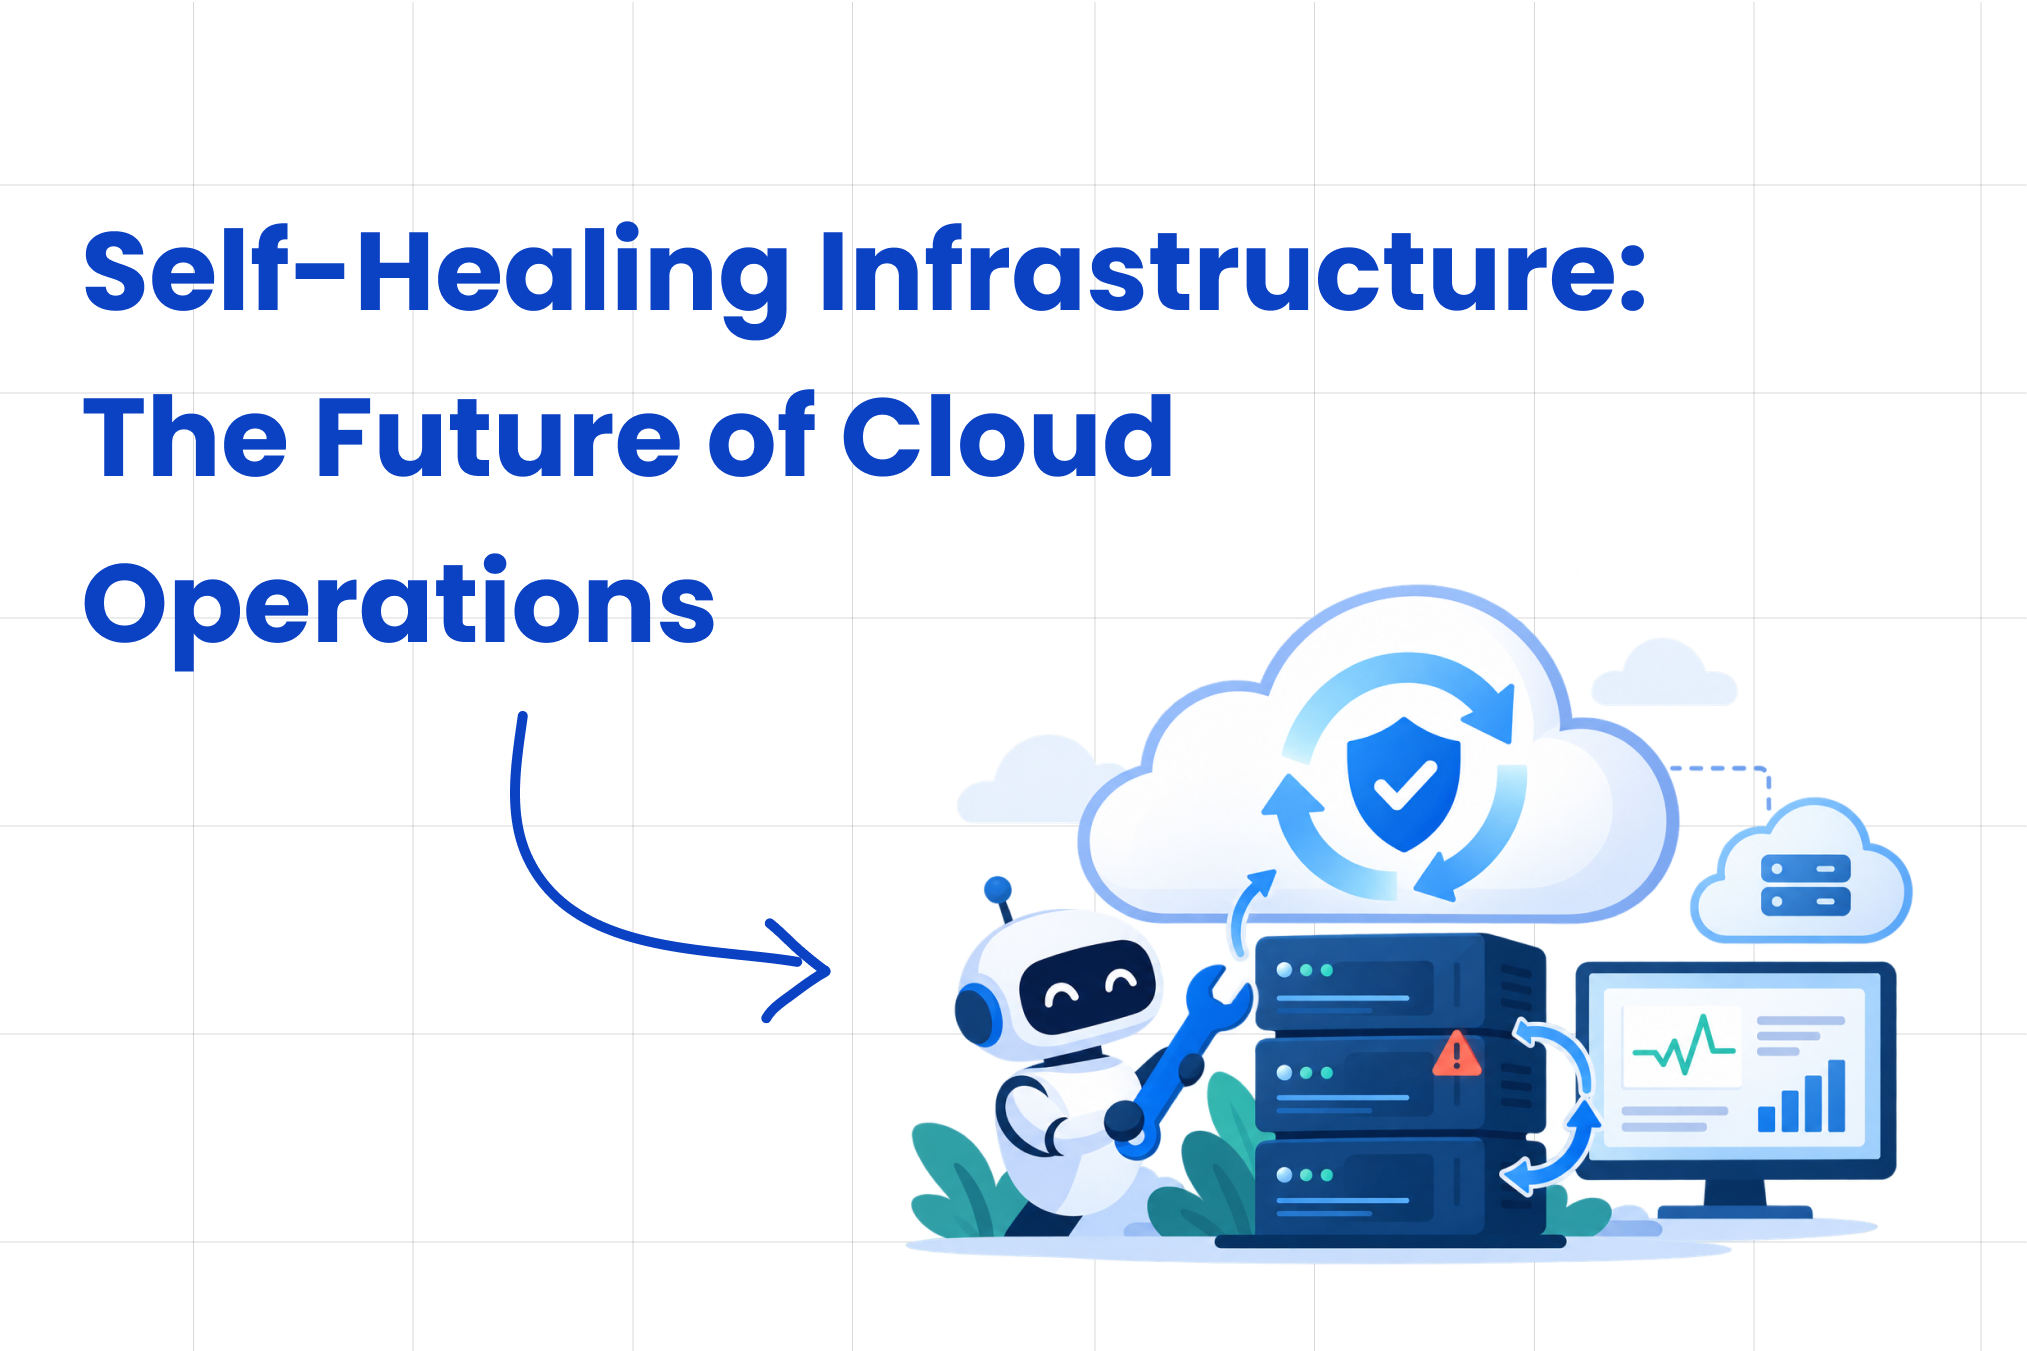
This is where Self-Healing Infrastructure is becoming an important idea in cloud operations.
Instead of waiting for an engineer to notice a problem and fix it, a self-healing environment can detect certain issues, understand what is happening, and take predefined action automatically. The aim is not to remove people from cloud operations. It is to help teams respond to common problems faster and keep systems running with less manual intervention.
Self-Healing Infrastructure refers to cloud systems that can automatically detect failures or unusual conditions and take corrective action.
The concept is similar to how some everyday systems respond to problems without human involvement. For example, when a device detects an issue, it may restart a service or switch to another working component.
In cloud operations, similar actions can happen across servers, containers, applications, databases, networks, and other infrastructure components.
Depending on how the system is designed, it may:
These actions are usually based on monitoring data, health checks, predefined rules, and automated workflows.
Cloud infrastructure can contain hundreds or even thousands of connected resources. Monitoring all of them manually is not practical, especially when problems can happen at any time.
Imagine an application running on several servers. One server suddenly stops responding at 2 a.m. An operations engineer may need to receive an alert, investigate the problem, identify the affected resource, and restore the service.
With automated cloud recovery, some of these steps can happen without waiting for someone to respond.
The system may identify the unhealthy server, remove it from service, start another instance, and redirect traffic to healthy resources.
This does not mean every cloud problem can or should be fixed automatically. More serious incidents still require experienced engineers. The value of self-healing is that it can handle predictable problems quickly while allowing technical teams to focus on issues that need deeper investigation.
A self-healing environment needs reliable information before it can take action.
Monitoring tools collect signals from different parts of the infrastructure. These can include CPU usage, memory consumption, application errors, network performance, service health, response times, and availability.
The system can then compare these signals against defined conditions.
For example:
Monitor → Detect → Decide → Act → Verify
If a service stops responding, the system detects the failure. It then checks the conditions that have been defined for that type of problem. If an automated response is appropriate, it takes action and checks whether the service has recovered.
This continuous process is what makes intelligent infrastructure different from simple automation.
Automation is not new to cloud computing. Businesses have been using scripts and automated workflows for years.
The difference is that intelligent infrastructure aims to make those automated systems more responsive to what is happening in the environment.
A basic automation rule might say:
“If memory usage reaches a certain level, restart the service.”
A more advanced system can consider several signals before deciding what to do. It might look at memory usage, application errors, traffic levels, recent deployments, and service health before taking action.
This can reduce unnecessary automated responses.
The system becomes less dependent on one simple trigger and more focused on the condition of the overall environment.
Most traditional infrastructure responses are reactive. Something goes wrong, and the team responds.
Predictive maintenance takes a different approach. It uses historical data and current system behavior to identify signs that a problem may occur in the future.
For example, a system might notice that a particular resource has shown unusual behavior several times before previous failures. Instead of waiting for the resource to stop working, the system can alert the operations team or take preventive action.
This could include moving workloads, replacing a resource, adjusting capacity, or scheduling maintenance.
Predictive capabilities can become especially useful in large cloud environments where small performance changes may be difficult for people to notice manually.
Behind most self-healing systems is a strong foundation of infrastructure automation.
Infrastructure needs to be created, configured, monitored, updated, and replaced consistently. Automation makes these tasks repeatable.
For example, if a cloud server fails, a self-healing process may need to create a replacement with the correct configuration. If this setup has been automated properly, the replacement can be created without an engineer manually configuring every component.
Infrastructure automation can cover areas such as:
The more consistent these processes are, the easier it becomes to build reliable self-healing workflows.
There is a common misunderstanding around Self-Healing Infrastructure. It does not mean that an organization should allow its cloud environment to make unrestricted decisions.
Automation needs boundaries.
A simple service restart may be safe to automate. A database change or major infrastructure modification may require human approval.
This is why good self-healing systems use defined policies and permissions. They should know which actions they can perform automatically and which situations should be passed to an engineer.
A useful model is:
Low-risk issue → Automatic action
Medium-risk issue → Automatic action + alert
High-risk issue → Human approval
This balance helps businesses gain the benefits of automation without losing operational control.
Self-healing systems can support many cloud workloads.
For customer-facing applications, automatic recovery can help reduce the impact of service failures. In containerized environments, unhealthy workloads can be replaced automatically.
For businesses running APIs, automated systems can respond to service failures and capacity problems. E-commerce platforms can also benefit when traffic changes quickly during sales or seasonal events.
Large enterprises can use self-healing capabilities across cloud infrastructure, especially when multiple environments need continuous monitoring.
The exact implementation depends on the application and its operational requirements.
A self-healing system has permission to make changes, which means security cannot be treated as a secondary concern.
Every automated action should have clearly defined permissions. Access should be limited to the resources and operations the system actually needs.
Organizations should also maintain logs of automated actions. Teams need to know what happened, why an action was triggered, and whether the recovery was successful.
Without proper visibility, automation can create new problems instead of solving existing ones.
Security checks, access controls, logging, and approval mechanisms should therefore be part of the self-healing design from the beginning.
Self-healing technology is designed to reduce repetitive operational work, not eliminate cloud engineers.
People are still needed to design recovery policies, investigate unusual failures, improve infrastructure, review automated actions, and handle complex incidents.
In fact, automation can give engineering teams more time for important work.
Instead of repeatedly responding to the same service restart or resource failure, engineers can focus on improving architecture, security, performance, and reliability.
This is one of the biggest advantages of Self-Healing Infrastructure. It changes where human attention is needed.
Cloud operations are moving toward environments that can observe themselves, respond to known problems, and learn from past system behavior.
The combination of monitoring, infrastructure automation, predictive maintenance, and intelligent infrastructure can make cloud environments more responsive.
Future systems may become better at identifying early warning signs, choosing appropriate recovery actions, and verifying whether those actions actually solved the problem.
However, successful self-healing will depend on good architecture and reliable data. Automation cannot compensate for poorly designed systems or unclear operational policies.
The real value of Self-Healing Infrastructure is not simply that machines can fix themselves. It is about creating cloud environments that can respond quickly when something goes wrong.
With automated cloud recovery, businesses can reduce the time spent responding to common failures. With infrastructure automation, teams can create consistent recovery processes. Predictive maintenance can help identify potential problems earlier, while intelligent infrastructure can bring more context into automated decisions.
Together, these technologies can contribute to better cloud reliability and more efficient operations.
Self-healing will not replace skilled cloud teams. Instead, it can become another tool that helps them build and operate systems that are more resilient, responsive, and prepared for unexpected problems.



 India

 Canada
 United Kingdom
 New Zealand
 USA
 UAE
 SGP
 Australia
 CALL
NOW