IT environments are no longer limited to a few servers and applications running inside an office. Businesses now depend on cloud platforms, containers, APIs, databases, SaaS applications, networks, and many other connected systems. While this technology gives companies more flexibility, it also makes IT operations harder to manage.
A problem in one system can affect several others. A slow database can make an application appear unavailable. A network issue can create multiple alerts. A sudden increase in traffic can put pressure on servers and impact users.
This is where AIOps can make a difference.
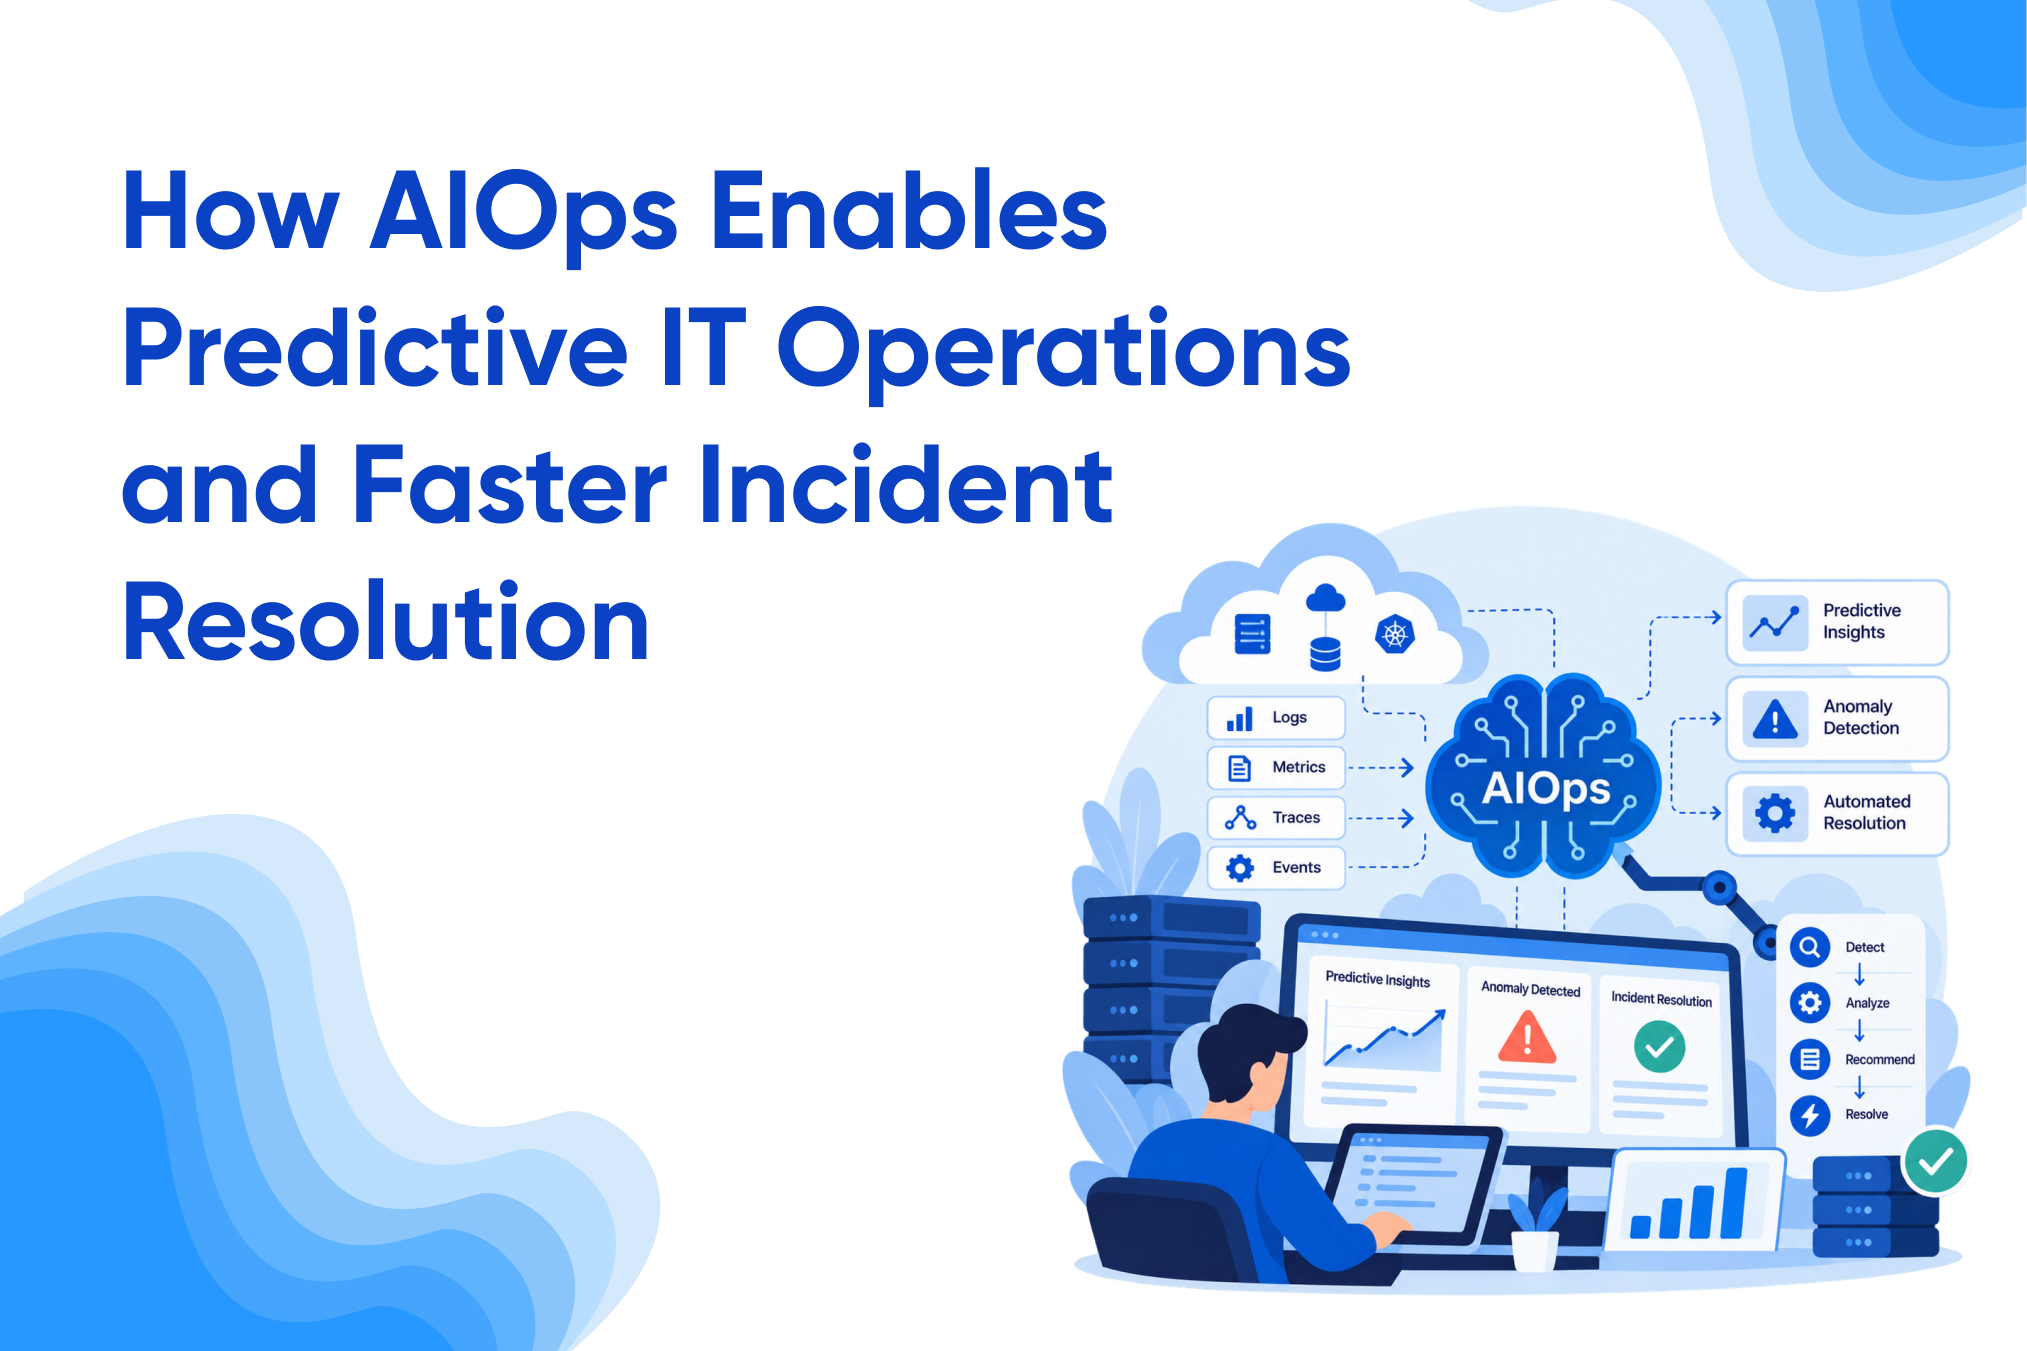
By bringing artificial intelligence, machine learning, monitoring data, and automation together, AIOps helps IT teams understand what is happening across their environments. More importantly, it can help them identify warning signs before they turn into major incidents and respond to problems faster when they occur.
AIOps stands for Artificial Intelligence for IT Operations. It uses AI and machine learning techniques to analyze large amounts of operational data generated by IT systems.
This data can come from application logs, infrastructure monitoring tools, network systems, cloud platforms, security tools, and other sources.
Instead of asking IT teams to manually review every alert or log entry, AIOps can analyze the information and identify relationships between different events.
For example, several servers may show increased response times at the same time that a particular database begins experiencing higher load. Individually, these events may look unrelated. An AIOps platform can connect them and help identify a possible common cause.
This gives operations teams more useful information when investigating problems.
Traditional IT operations often follow a simple pattern: something fails, an alert is generated, and an engineer starts investigating.
That approach still has value, but modern systems generate so much operational data that teams may find it difficult to identify important signals quickly.
Predictive IT operations takes a more proactive approach.
Instead of waiting for an outage, AIOps can study historical and real-time data to identify patterns that may indicate an upcoming problem.
For instance, an application may show gradually increasing response times over several days. At the same time, memory consumption may continue rising. These changes may not immediately cause an outage, but together they could indicate that the application is heading toward a performance problem.
AIOps can identify such patterns and bring them to the attention of the operations team.
The goal is simple: find potential problems earlier so teams have more time to act.
One of the important capabilities of AIOps is anomaly detection.
IT systems produce normal patterns. Server usage may increase during working hours, application traffic may rise during certain periods, and database activity may follow predictable trends.
A simple threshold-based monitoring system may generate alerts whenever a value crosses a fixed limit. But not every unusual event fits neatly into a predefined threshold.
AIOps can learn normal patterns and identify activity that differs significantly from them.
For example, if an application normally receives a certain level of traffic at night but suddenly experiences an unusual increase, AIOps can flag the behavior.
Anomaly detection can also help identify:
This helps teams pay attention to meaningful changes instead of treating every alert as equally important.
Alert fatigue is a common challenge for IT teams.
Large environments can generate hundreds or thousands of alerts. Many may be connected to the same underlying problem.
For example, a network failure could cause multiple applications to become unavailable. Each application might generate its own alert, even though the original problem is the network.
Without proper correlation, an engineer may see dozens of alerts and assume there are dozens of separate issues.
AIOps solutions can group related events and identify possible relationships between them.
Instead of presenting every alert independently, the system can help create a clearer picture of the incident.
This allows engineers to spend less time sorting through notifications and more time working on the actual problem.
Finding an incident is only part of the job. The next challenge is resolving it.
This is where automated incident response becomes useful.
Once an AIOps system identifies a known type of issue, it can trigger predefined actions. Depending on the organization's rules, these actions might include restarting a service, creating additional resources, running a diagnostic process, or notifying the appropriate team.
For example, if a particular application repeatedly becomes unresponsive because of a known service condition, an automated workflow could restart the service and then check whether performance has returned to normal.
If the automated action works, the incident may be resolved without requiring an engineer to perform the same steps manually.
For more complex incidents, AIOps can provide recommendations while leaving the final decision to a human.
One of the biggest benefits of AIOps is its ability to help teams investigate the relationship between events.
Consider an online application that suddenly becomes slow. The first alert may point to the application itself. But the real problem could be an overloaded database, network latency, a cloud resource issue, or another connected service.
AIOps can analyze data from different systems and help identify which event may have started the chain of problems.
This type of analysis can support faster root-cause investigation.
Instead of asking, “Which alert should we fix first?” teams can ask, “What caused these alerts to appear together?”
That difference can significantly improve incident handling.
Modern IT operations management involves much more than keeping servers running. Teams need to monitor applications, cloud resources, networks, databases, user experience, and business services.
AIOps can bring information from these different areas into a more connected operational view.
This can help teams understand how technical events affect applications and business services.
For example, a minor infrastructure issue may not matter if it has no impact on users. On the other hand, a small change in an important customer-facing application may deserve immediate attention.
AIOps can help operations teams prioritize issues based on their wider impact rather than simply responding to alerts in the order they arrive.
AIOps is sometimes described as a way to automate IT operations completely. In practice, that is not the best way to look at it.
IT teams still need to design systems, investigate complex failures, make architectural decisions, manage risks, and determine which actions should be automated.
AIOps works best when it supports these responsibilities.
Routine and well-understood incidents can be handled automatically, while unusual or high-risk problems can be escalated to experienced engineers.
This creates a balance between automation and human decision-making.
Organizations considering AIOps solutions should look beyond the AI label.
The technology should work with the tools already used by the IT team. It should be able to collect useful data, connect events across different systems, and provide information that engineers can actually use.
Businesses should also consider:
Integration with existing monitoring and cloud tools
The purpose should always be to solve real operational problems rather than introduce another complicated tool.
As IT environments continue to grow, simply collecting more monitoring data will not be enough. Teams need better ways to understand that information and decide what requires attention.
This is where AIOps can become increasingly valuable.
By combining anomaly detection, predictive analysis, event correlation, and automated incident response, AIOps can help organizations move from reactive support toward more proactive operations.
The future of IT operations management is likely to involve systems that can recognize unusual behavior, identify potential risks, recommend actions, and automatically resolve known problems.
For businesses, the result can be fewer disruptions, faster incident resolution, and more time for IT teams to focus on improving the technology that supports the organization.
AIOps is not simply about adding AI to monitoring tools. Its real value comes from turning large amounts of operational data into useful decisions and timely action.



 India

 Canada
 United Kingdom
 New Zealand
 USA
 UAE
 SGP
 Australia
 CALL
NOW